Case Study / 2026
Sellable
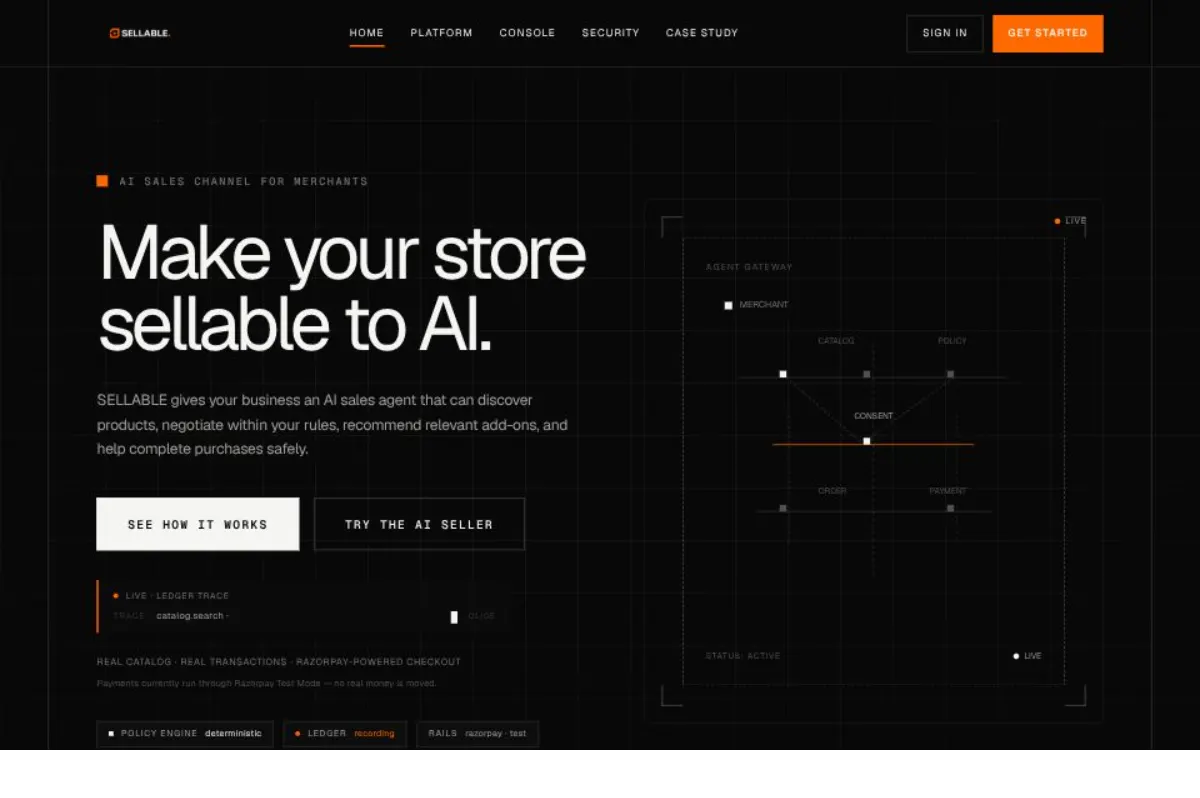
Sellable lets AI agents buy stuff on their own, with guardrails that actually hold. They get a storefront they can read: find products, haggle quotes, pass policy checks, and pay over real Razorpay rails. Every decision lands in an audit ledger. The model suggests, deterministic code decides.


 Next.js 16


 Razorpay
Project Features
What this case study includes
05 features
The problem
An AI agent with a credit card and no guardrails is a bad idea. The question I started with: the model that picks what to buy should not be the thing that decides whether the purchase is allowed.
Sellable is the commerce layer I built around that answer. Pricing rules, spend limits, consent, order state, payment verification, and audit logging all live outside the LLM. The model can propose an action; deterministic code decides whether it happens.
How a transaction flows
- Discovery through agent manifests, llms.txt, and a machine-readable catalog
- Bounded quote negotiation between LangGraph seller and buyer agents
- Policy engine verdicts on budget, floor price, stock, and negotiation rounds
- Single-use consent, human-in-the-loop approval for high-value orders
- Razorpay test-mode payment with webhook reconciliation and refunds
- Every material action recorded in the append-only XAI Ledger
Architecture
Next.js 16 frontend, FastAPI backend, Supabase for data. The agent gateway exposes machine-readable discovery through an HMAC-signed transactional API: agent manifests, llms.txt, and a machine-readable catalog. Sellable is built for AI buyers, so the storefront is readable by agents directly.
Two LangGraph agents, one buyer and one seller, negotiate quotes inside bounds the policy layer sets. The agents talk; the policy engine has veto power over every material step.
The policy and evaluation layer
The policy engine is LLM-independent. It reads the transaction state and returns verdicts: budget ok or not, floor price respected or not, stock available or not, negotiation rounds exhausted or not. Single-use consent is issued per transaction, spend caps are enforced per agent, and orders above the human-in-the-loop threshold stop and wait for approval.
Payments run over Razorpay test-mode rails with webhook reconciliation, refunds, and idempotent orders. Every material action lands in the append-only XAI Ledger with a reasoning summary, so a rejected order can be read back and explained.
Changes are measured against 7 deterministic transaction scenarios: evaluation-driven development, the same idea described in the loop engineering article.
Limitations
- Payments are on Razorpay test mode. No real money moves yet.
- The policy checks are the ones I thought of. TODO(mahir): which real-world cases slip through today (partial refunds? currency? stock races?).
- TODO(mahir): what the 7 eval scenarios actually cover and which one has bitten you.
What I learned
TODO(mahir): only you know this section. Useful prompts: what broke while you wired webhooks to the ledger, what surprised you about agent negotiation, what you would change if you rebuilt the policy engine.
Links
- Live app: sellable.shop
- Source code: github.com/mahirmlk/sellable
- Design pattern: Context vs Loop vs Harness Engineering (permissions, evaluator, checkpoints)
- Typed decisions beside hard tests: Jev Explained